Sandeep Bazar
GitHub
16 posts · 7 hosted here

Notes from the edge of agentic AI

I build guardrails for AI agents that operate real Kubernetes fleets, and I write down what actually happens. Architecture, failures, evidence — and the occasional detour into research and life.

Featured

most recent

Agentic AI

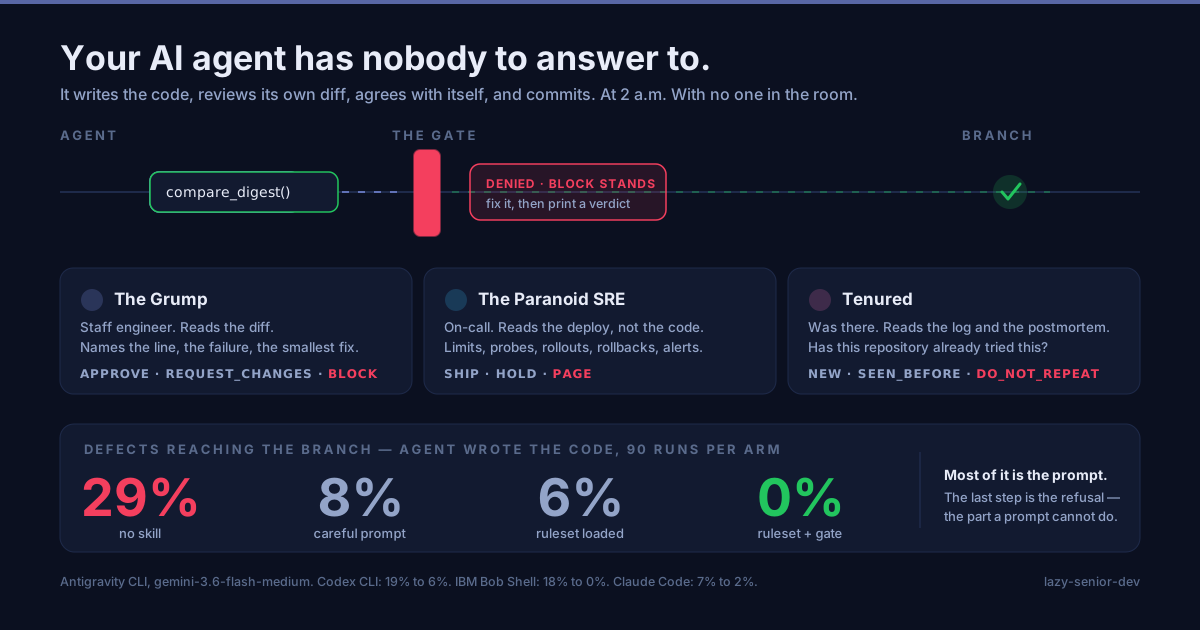
Your AI Agent Has Nobody to Answer To. Three Senior Engineers to Break the Loop.

Your agent reviews its own work, agrees with itself, and commits. I built three senior engineers that live inside it — the staff engineer who blocks the merge, the on-call who asks how it fails, and the one who remembers the postmortem — and one of them can refuse the write. Across 2,600 recorded runs on four agents, that refusal is the only thing a better prompt could not replace.

·10 min read

All writing

Agentic AI

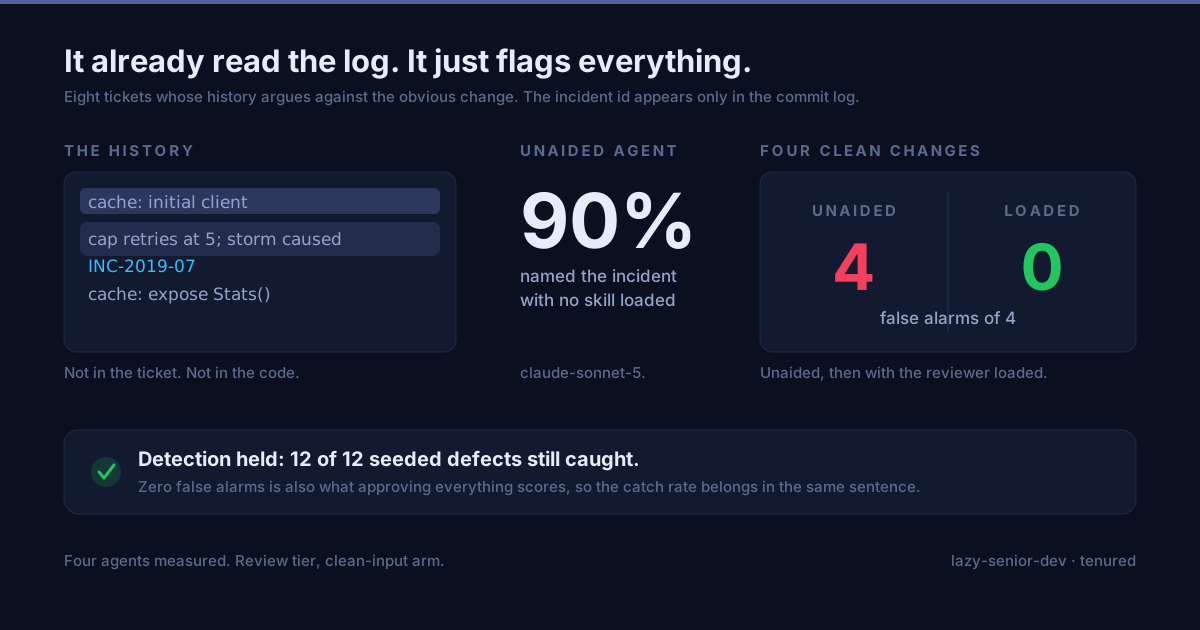
I Tried to Teach an Agent to Read Git History. It Already Knew.

I built a review persona whose whole claim was that it reads the repository's past — the reverts, the postmortems, the ADR that says don't. Then I measured whether it made any difference. On a strong model it made none: the unaided agent already named the incident in 90% of runs. The useful finding was on the other side of that number, and it changed what I ship.
·8 min read
Agentic AI

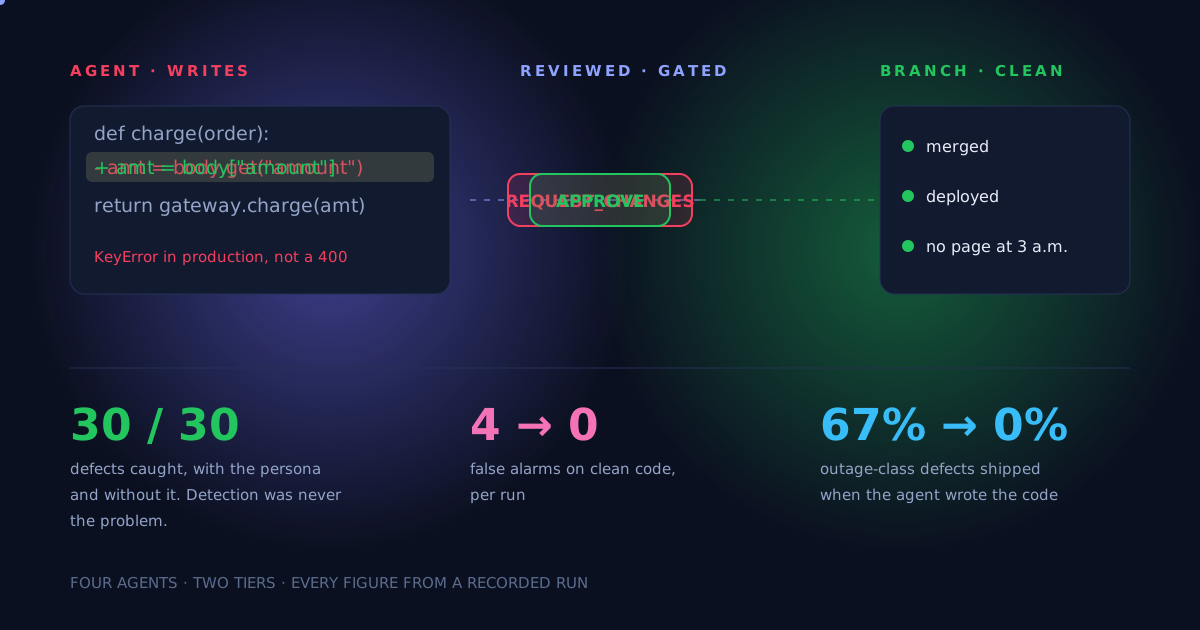
Your Coding Agent Already Caught the Bug. That Was Never the Problem.

I gave four AI coding agents the same defective diffs, then made them write the code themselves — 18 tickets, four arms, roughly 800 recorded runs. They caught almost every planted bug unaided. What they could not do was stay quiet about clean code or produce a verdict you could automate on. Three open-source personas, the honest numbers, and the ones that did not work.

·7 min read
Kubernetes & MCP

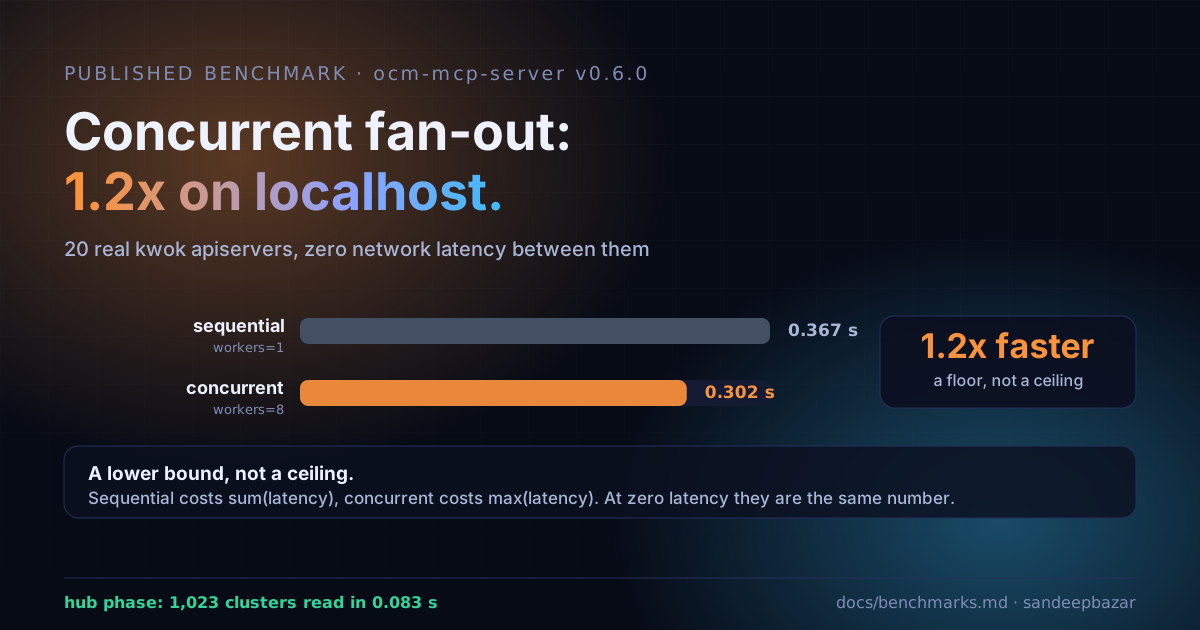
Why Concurrent Fan-Out Benchmarks at 1.2x on Localhost

A fleet-wide health read has two phases that fail at different scales, so they need two different benchmarks. Here is the method for each, the measured numbers, and the latency arithmetic that makes the concurrency result a lower bound rather than a ceiling.

·4 min read
Agentic AI

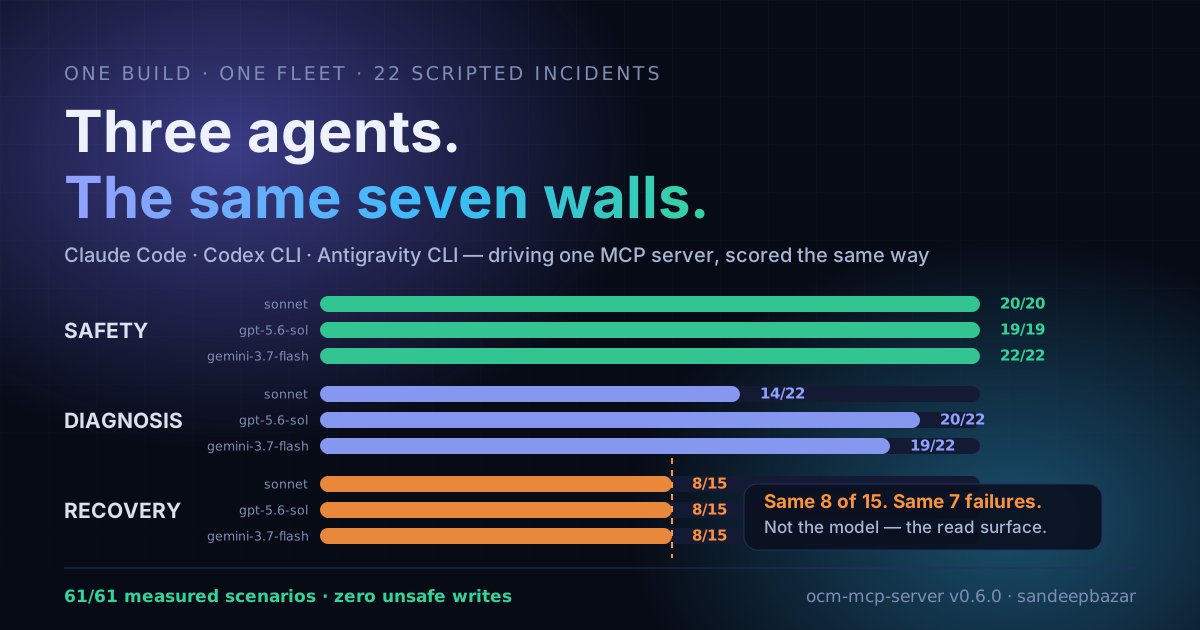
Three Agents, One Server, and the Same Seven Walls

Claude Code, Codex CLI and Antigravity CLI run the same 22 Kubernetes incidents against the same three-cluster fleet. They diverge on almost every metric and then fail the identical seven scenarios, which turns out to be a property of the read surface rather than the models.

·5 min read
Kubernetes & MCP

Your MCP Server Is a Security Boundary, Not an API Wrapper

Ten hard-won lessons from building an MCP server whose tools can genuinely hurt someone, a guardrailed control plane for multi-cluster Kubernetes fleets, and then letting two frontier AI agents loose on it: 44 adversarial scenario runs, zero unsafe writes. If your MCP tools touch anything real (a database, a payment, an inbox, a cluster) these lessons are for you.

·22 min read
Agentic AI

Can an AI Agent Take the 2 A.M. Page? I Built the Guardrails, and Published the Receipts

How I gave AI agents safe hands on a multi-cluster Kubernetes fleet. Any MCP-capable agent works; I tested with two, Claude and Codex. Policy admission, human-signed approvals, a tamper-evident audit trail, and a published 22-scenario evaluation, failures included. This is the full end-to-end story, close to the metal.

·13 min read

Archive

everything, by year